
MiMo-V2.6 Puts MIT Omnimodal MoE Weights Online After Scaled RL Runs
Xiaomi’s MiMo team published MiMo-V2.6-Pro-RL and MiMo-V2.6-Flash-RL on Hugging Face under MIT—native text/image/video/audio MoE checkpoints with a claimed 1M-token context—alongside RL training disclosures updated on Xiaomi’s docs on September 22, 2026.
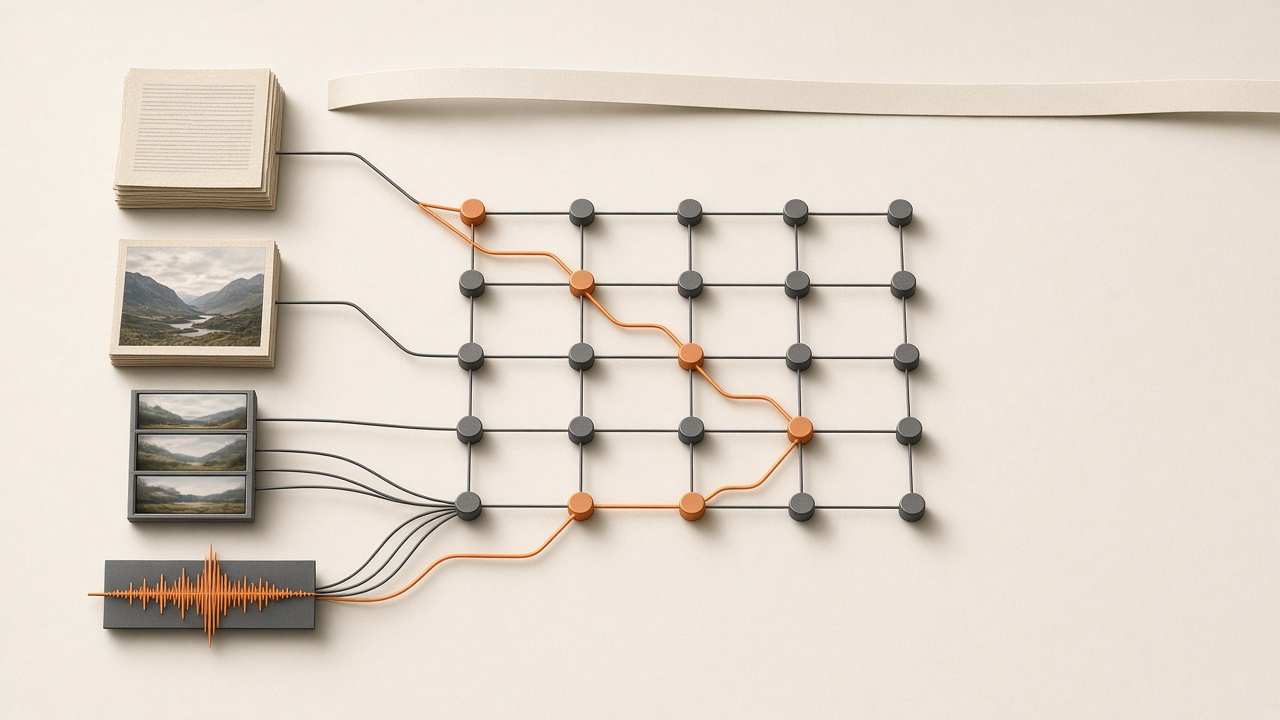
Xiaomi’s MiMo team published ungated Hugging Face checkpoints for MiMo-V2.6-Pro-RL and MiMo-V2.6-Flash-RL under an MIT license around September 21, 2026, and updated its official MiMo launch page on September 22 to document the release plus the accompanying reinforcement-learning package. Both cards describe native omnimodal models that accept text, image, video, and audio in one network, with a claimed one-million-token context aimed at long repositories, tool traces, and multi-session agent runs. Flash is listed as a sparse mixture-of-experts model at 309 billion total parameters with 15 billion activated; Pro is listed at 1.02 trillion total with 42 billion activated. The Flash README front matter sets license: mit, matching the commercial MIT framing used for the series.
The distinctive part of the news is not only that the weights exist. Xiaomi is framing V2.6 as a public test of large-scale reinforcement learning on verifiable agent tasks, and it says it is releasing the technical report, training environments, and RL code alongside the checkpoints. Xiaomi’s docs treat that packaging as central: downloadable MoE weights plus the machinery used to train them, rather than a model card alone.
Pro versus Flash on the cards
Both Pro and Flash share the same high-level architecture story on Hugging Face. Each card lists a 681-million-parameter MiMo vision encoder, an audio stack built from a 308-million-parameter AudioTokenizer plus a 127-million-parameter audio patch encoder, and a five-layer multi-token-prediction speculative decoder. The backbone difference is scale: Flash uses a smaller sparse MoE footprint for efficiency-balanced serving, while Pro is positioned as the flagship. Serving notes on the cards point operators toward SGLang and a MiMo-aware vLLM image, with multi-node recipes called out for Pro. Hosted paths listed on the cards and docs include Xiaomi AI Studio, MiMo Desktop, MiMo Code, the MiMo Open Platform API, and OpenRouter.
Xiaomi’s launch page says the V2.6 series keeps the same API pricing as V2.5, and that Pro also offers an UltraSpeed mode on the open platform and desktop client for latency-sensitive work. Those hosted SKUs are separate from the open weights; the MIT claim applies to the published checkpoints. The checkpoints are MIT-licensed and permit commercial use; cluster-scale MoE serving remains hardware-intensive, especially for the trillion-parameter Pro configuration.
What Xiaomi disclosed about the RL phase
Xiaomi says Flash and Pro each completed 30 RL steps in under six days. The model cards describe asynchronous Group Relative Policy Optimization on very large batches—1,568 prompts × 16 rollouts per step—or roughly 750,000 trajectories over 30 steps. The company reports training costs of about $850,000 for Flash and $2.62 million for Pro for that phase, and it says average pass rates on training tasks rose by about 25% and 12% respectively during the run. Xiaomi also reports DeepSWE v1.1 gains during RL of roughly 17 points for Flash and 14 points for Pro on the out-of-sample software-engineering evaluation it cites; finished-card DeepSWE numbers differ slightly from those live-training deltas and should be read as author-reported tables, not independent reruns.
The launch page describes three scaling axes: larger batch size and asynchronous throughput that can train with million-token context, a multi-task mix spanning code, general agents, visual work, and cybersecurity, and greater grader compute that ranks trajectories within groups rather than relying only on binary pass/fail. Xiaomi says it froze the MoE router during scaled training to limit expert-load drift and used reward-hacking defenses spanning reward design, adversarial evaluation, anomaly detection, and verifier cross-checks. The open package also includes a Distill-Qwen-9B starting point plus thousands of RL task environments and an end-to-end training framework built on verl and related agent tooling, according to the same docs.
How to read the score tables
Vendor tables on the cards and docs place Pro near Claude Opus 5 and GPT-5.6 Sol on several agent benchmarks Xiaomi reports, while still trailing the strongest closed models Xiaomi itself names on Artificial Analysis’s composite index. Treat DeepSWE, Artificial Analysis, Terminal Bench, and related figures as Xiaomi-reported unless independently republished.
For open-source operators, the practical takeaway is narrower and more durable than any single leaderboard row. MIT commercial weights for two native omnimodal MoE sizes are live at XiaomiMiMo/MiMo-V2.6-Flash-RL and XiaomiMiMo/MiMo-V2.6-Pro-RL, the official docs dated September 22 describe the RL recipe and supporting code release, and hosted API access is available at V2.5 pricing if self-hosting a 15B-active or 42B-active MoE is not the goal.
- #Products
- #Opensource
- #AI Agents

Author
Raj M
Contributor
AI Systems Architect is a seasoned technology leader with over 15 years of experience in the IT industry working with Fortune 500 companies. With a solid foundation in multi-agent systems, open-source LLM infrastructure, and enterprise deployment, he excels at building scalable production-grade AI platforms.