
Trident Puts Text, Images and Fused Docs in One Ranking, and Names the Bias It Fixes
OpenBMB released Trident-Qwen3VL-2B on October 12, 2026, a MIT-licensed multimodal embedder fine-tuned from Qwen3-VL-2B-Instruct that ranks text-only, image-only and fused documents together while targeting modality preference.
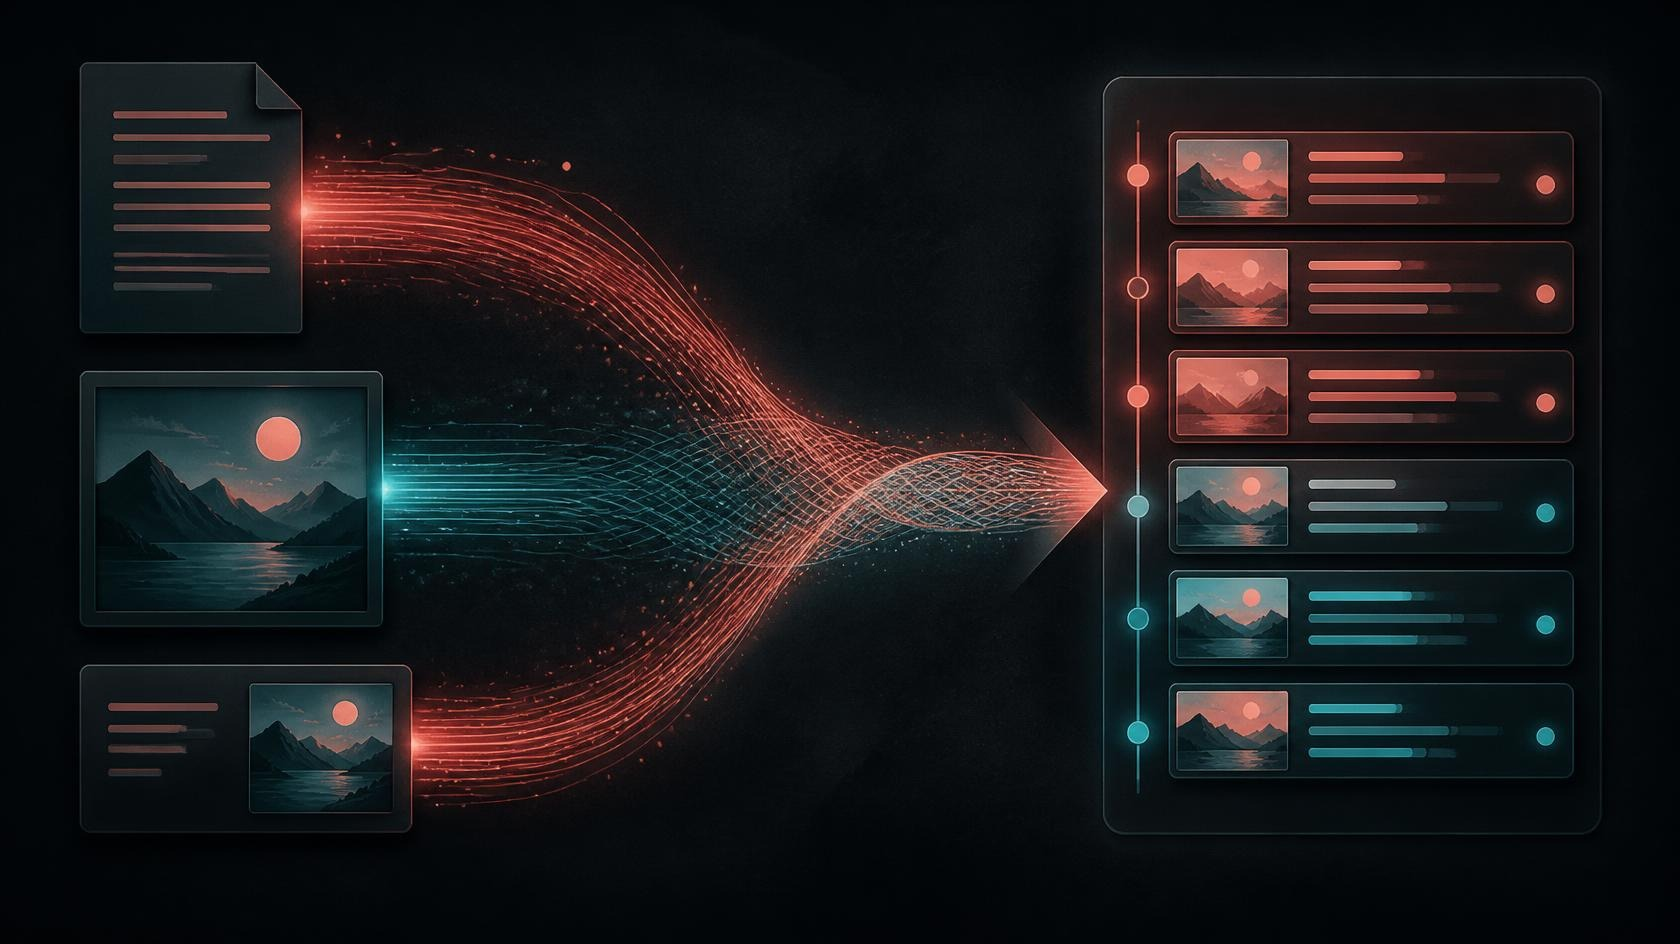
OpenBMB has published Trident-Qwen3VL-2B, a 2-billion-parameter multimodal embedding model built for corpora that mix text, images and fused text-image documents. The Hugging Face repo OpenBMB/Trident-Qwen3VL-2B was created on October 12, 2026 at 10:25 UTC (3:55 PM IST). The weights are fine-tuned from Qwen/Qwen3-VL-2B-Instruct, the LoRA adapter is already merged, and the accompanying code lives at OpenBMB/Trident under the MIT License. Training and evaluation datasets ship as OpenBMB/Trident-Train and OpenBMB/Trident-Eval.
The paper behind the release, arXiv 2610.11816, went up on October 8, 2026 under the title “Chaos in the Text: Revealing the Modality Preference in Mixed-Modality Retrievers.” The model card treats that paper as the official description of the method.
The V-shaped failure mode
Dense retrievers already work well on text-only or image-only collections. The authors ask what happens when those collections are mixed. Their abstract reports a pronounced V-shaped curve: performance stays strong on single-modality corpora, then drops when modalities coexist. As image documents are replaced with semantically matching text, retrieval degrades, then recovers once the corpus is text-only again.
The sharper claim is about which distractor hurts more. Irrelevant text, they write, causes more severe degradation than an equal number of irrelevant images. They call that pattern Chaos in the Text. Further analysis points to modality preference: text representations receive systematically higher similarity scores, so irrelevant text can outrank a relevant image even when the image is the better answer.
That is a practical problem for product search, visual document retrieval and any agent that must rank a screenshot next to a caption next to a chart that contains both.
How Trident balances the three views
Trident’s answer is to treat three views of each document as co-equal positives: text-only, image-only and fused text-image. Training jointly optimizes relevance discrimination and positive-view balance through what the paper calls Multi-Positive View InfoNCE. The goal is not only to pull the right document up, but to keep the three views of the same document from fighting each other in embedding space.
The released checkpoint is a VLM-based embedder on the Qwen3-VL-2B-Instruct trunk. Because the LoRA is merged, users do not need a separate base download or the PEFT stack to load it. The card states that Trident-specific contributions, including the fine-tuned weights, are MIT-licensed, while the Apache-2.0 terms of the Qwen3-VL base continue to apply to derived weights, and training images remain under their original dataset licenses.
Running a mixed ranking
The GitHub quickstart clones the Trident repo, installs requirements tested with Transformers 4.57.1 (Qwen3-VL needs 4.57 or newer), and downloads the Hub checkpoint. Encoding goes through TridentQwen3VLBackend. Each item is a dict with optional text and an images list of local paths. Queries and documents use different default instructions, which are part of the training format. Embeddings come back L2-normalised, so a simple matrix multiply yields cosine scores that are meant to be comparable across text-only, image-only and fused documents in one list.
The README example ranks three documents for one finance-chart question: a text description, an image alone, and a short caption plus the same image. That is the mixed-modality case the paper says ordinary retrievers mishandle.
What the experiments claim
Across visual-document and natural-image benchmarks, the abstract says Trident improves mixed-modality retrieval on both CLIP-based and VLM-based architectures, reduces sensitivity to modality composition and text distractors, and raises average single-modality retrieval as well. Those are the authors’ reported outcomes; independent third-party leaderboards are not part of this release note.
The author list on arXiv 2610.11816 includes researchers from OpenBMB-affiliated groups; the GitHub tree’s October 12 commit added the Trident-Qwen3VL-2B weights alongside the Trident-Train and Trident-Eval dataset pointers, after an October 10 commit that opened the training and evaluation code. That sequencing matters for freshness: the method paper appeared October 8, and the runnable 2B checkpoint followed four days later.
For teams already running separate text and vision indexes, Trident is interesting less as another 2B embedder and more as a concrete recipe for stopping text from quietly dominating a shared ranking. Anyone adapting it should still honor the base Qwen3-VL Apache-2.0 terms and the original licenses on training images called out on the model card. The October 12 weight drop, with merged LoRA and MIT code, makes the recipe runnable without reconstructing the training stack from the paper alone.
- #Trident
- #OpenBMB
- #Multimodal Embeddings
- #Qwen3-VL
- #MIT

Author
Raj M
Contributor
AI Systems Architect is a seasoned technology leader with over 15 years of experience in the IT industry working with Fortune 500 companies. With a solid foundation in multi-agent systems, open-source LLM infrastructure, and enterprise deployment, he excels at building scalable production-grade AI platforms.